PERSON DIRECTORY
Bryan Shan
Bryan Shan appears in 3 indexed conversations across SemiAnalysis. This directory brings every appearance, source, TL;DR, digest, and transcript into one searchable feed.
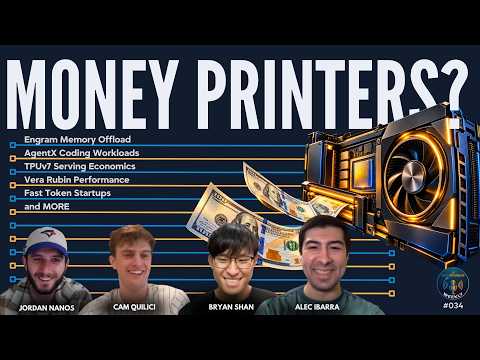
Ep. 034 - The Fight for Fast Tokens, TPU v7, Vera Rubin, and Engrams (AI Supply Chain, InferenceX)
Jordan NanosCam QuiliciBryan ShanAlec Ibarra
Engrams co-design model architecture and memory hierarchy, retrieving 2-gram and 3-gram embeddings from DRAM or SSD.Hybrid Engram-MoE layers outperform either endpoint, while AgentX traces show 100,000 input tokens at P50 and cache-hit rates above 98%.DRAM offload matters for hundreds of agents at 40–60 tokens/s; TPU V7's early Pareto position still leaves software, utilization, pricing, and demand unresolved.
Ep. 017 - DeepSeek V4 and Huawei Ascend NPU Performance (InferenceX) | Kimbo Chen, Cam Quilici, Bryan Shan, Jordan Nanos
Kimbo ChenCam QuiliciBryan ShanJordan Nanos
DeepSeek V4 changes inference economics by combining million-token context with roughly 100X lower KV-cache usage, while MegaMoE claims 1.5-1.73X speedups through communication-computation overlap.Huawei Ascend delivered credible release-day performance, but the larger catalyst is software iteration: AgentX will test realistic Claude Code traces, caching, and prefill-decode systems beyond synthetic chip benchmarks.
Ep. 002 - InferenceX 2.0 Release (Technical Staff) | Cam Quilici, Bryan Shan, Doug O'Laughlin, Jordan Nanos
Cam QuiliciBryan ShanDoug O'LaughlinJordan Nanos
InferenceX 2.0 shows GB200/GB300 delivering 20x DeepSeek-R1 throughput per GPU versus a fully tuned H100 at low interactivity, and 80–100x at 100 tokens/sec/user.NVLink’s 72-GPU domain, software optimization, and multi-token prediction drive the gap, while MI355’s roughly 25% TCO advantage over B200 highlights margin potential; composability, legacy fleets, and larger frontier models remain risks.